Project DoLittle
Whale bioacoustics, long-context models, and public release engineering.
DoLittle brings together CAIRN's public work on marine mammal communication: humpback and Orca datasets, long-context neural audio modeling, and the technical release materials needed to make the project legible to researchers outside the lab.
The project is intentionally split into two public surfaces: dataset work and model work. That makes the site more useful to readers who care about one side of the release more than the other, while still showing the broader research direction.
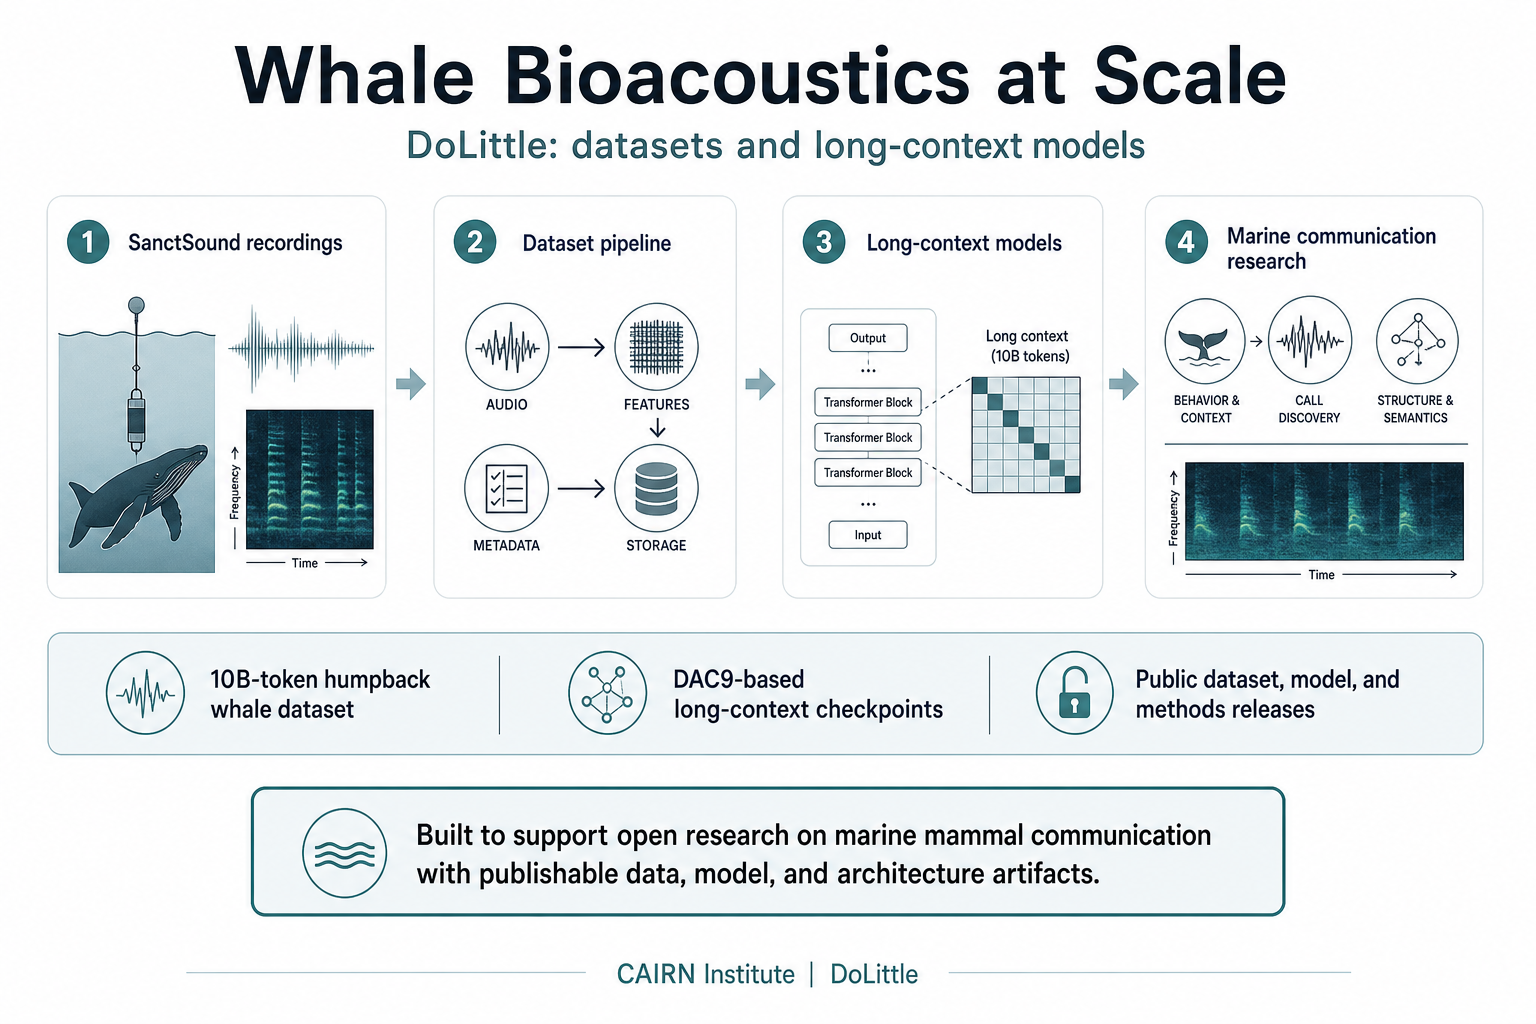
The detailed DoLittle public surface.
The public detail removed from the homepage belongs here: the scale of the dataset release, the model tracks, and the separation between dataset and model work.
Dataset Scale
DoLittle now publishes two complementary whale-data releases: roughly 10B humpback-song tokens from NOAA SanctSound and 500M DAC9 token IDs with source and processing provenance.
Model Release Tracks
DoLittle currently exposes 3 public model and methods release surfaces so readers can separate architecture, training behavior, and release notes.
Long-Context Focus
The strongest published model track pushes to 128K context, which is central to the project rather than an incidental implementation detail.
Two-Part Project Structure
Dataset and model work are intentionally split into separate public sections so the project stays legible to technical researchers following one side more closely.
Public whale dataset releases.
The dataset side of DoLittle now spans a large humpback training corpus from NOAA SanctSound and an auditable Orca token release. Both make source provenance, processing choices, and public-release documentation part of the research surface.
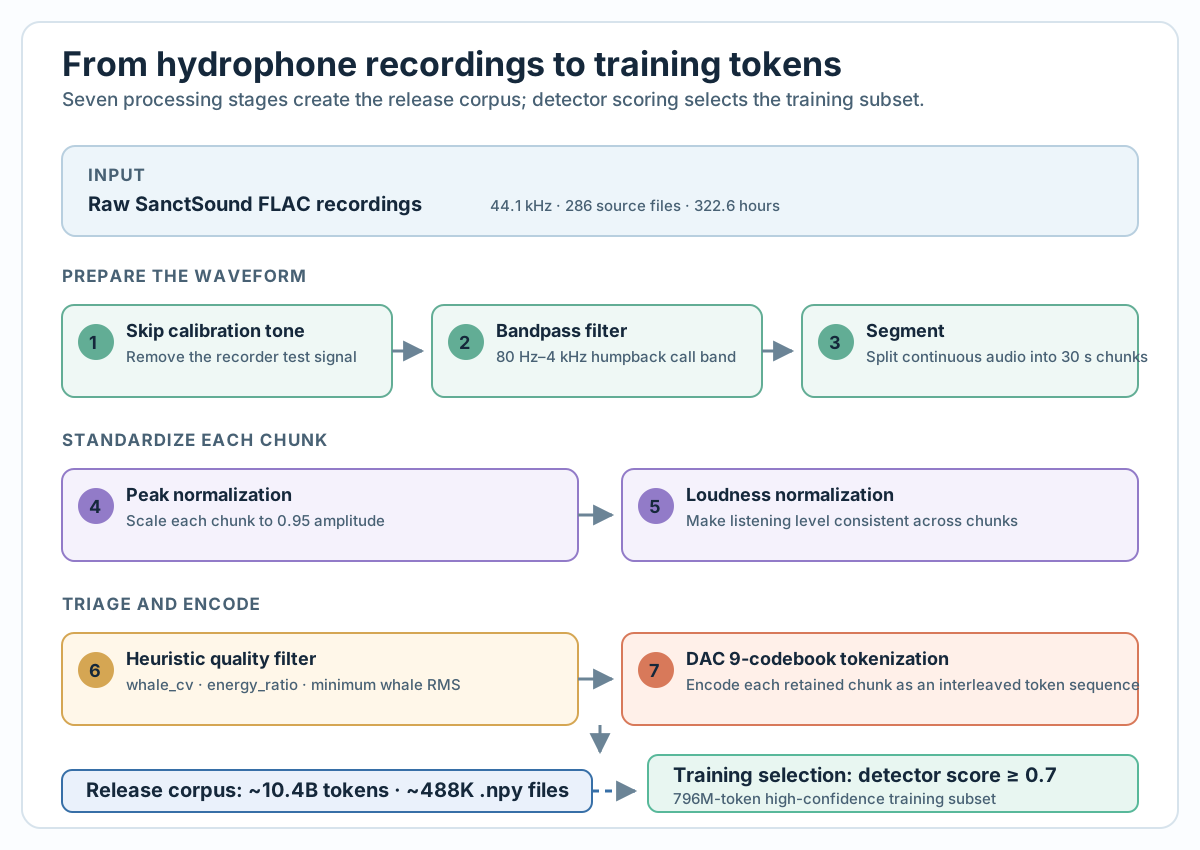
A concise view of the seven-stage data-processing flow behind the public release.
10B Token Humpback Dataset
Dataset Release Blog
Overview of the 10B-token humpback whale dataset, the processing pipeline, and why the tokenized release is useful for long-context marine-audio experiments.
Repository
The public DoLittle codebase and supporting technical materials tied to the dataset and model releases.
Hugging Face Dataset
The released humpback DAC9 corpus is also available on Hugging Face for direct inspection and dataset access.
500M Token Orca Dataset
Orca Token Dataset
An auditable release of 21,202 30-second Orca contexts and 500M DAC9 token IDs, with source and processing provenance retained.
Orca Dataset Packages
Three public packages preserve their source-license boundaries.
Orca Processing Utilities
Open utilities for quality scoring, manifest-driven preparation, DAC9 tokenization, checksums, and release assembly.
Long-context marine audio models.
The model side of DoLittle covers training, checkpoint release, architecture choices, and the implementation details that matter when the problem is long-context neural audio rather than conventional short-window acoustic classification.
Training and Release Blog
Detailed writeup of training runs, hardware constraints, loss behavior, and example generations from the DoLittle model family.
Architecture Notes
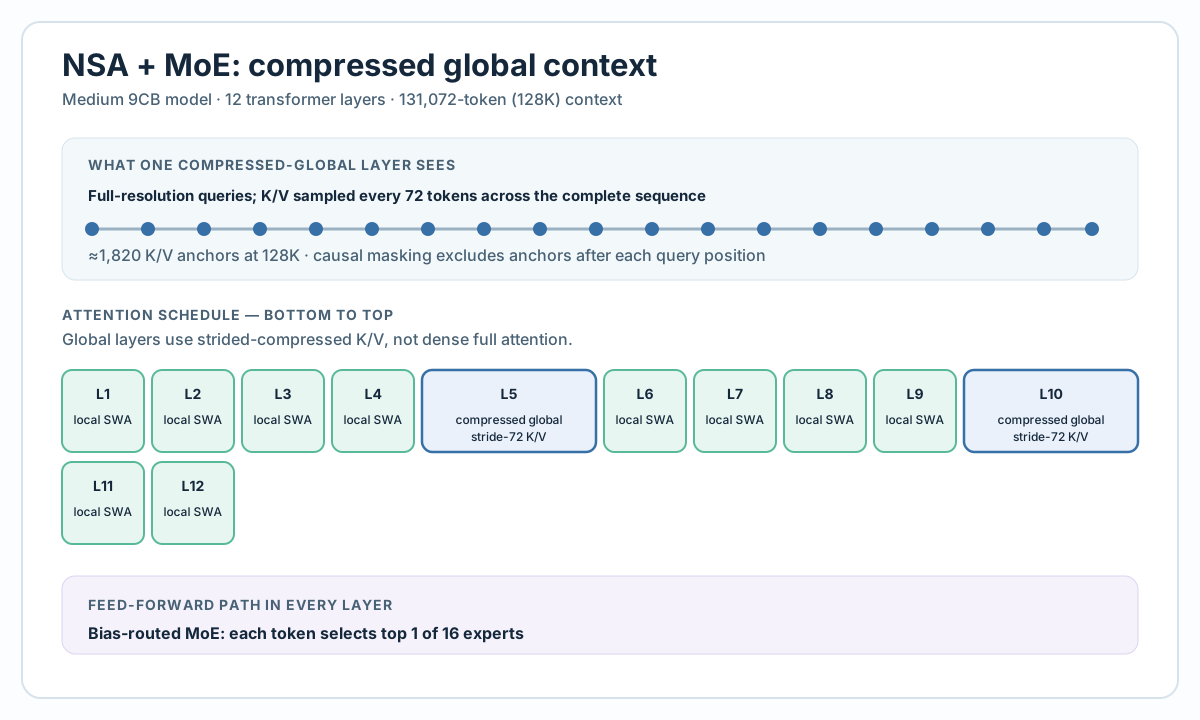
Technical notes on SWA+MoE and NSA+MoE design choices used to push context length while preserving a causal neural-audio decoder.
Technical Release Notes
Supporting notes on the released checkpoints, configuration, and implementation details needed for reproducibility.
Hugging Face Models
The released DoLittle model checkpoints are also available on Hugging Face for direct inspection and download.